Adaptive, Optimal, Robust, and Learning Control
These notes are from an advanced PhD course on adaptive, optimal, robust, and learning-based control at Uppsala University, taught by Dr. Christos Verginis and Dr. Aris Kanellopoulos. The main textbooks behind them are Ioannou and Sun’s “Robust Adaptive Control”, Khalil’s “Nonlinear Systems”, Kirk’s “Optimal Control Theory”, and Lewis, Vrabie, and Syrmos’s “Optimal Control”.
How to Read These Notes
Advanced control can look like a zoo of methods: MRAC, backstepping, LQR, MPC, $H_\infty$, reinforcement learning. These notes organize them around one question: what kind of uncertainty does the plant have, and what kind of guarantee do we need?
- Adaptive control learns structured uncertainty (unknown parameters) online while keeping the loop stable.
- Optimal control assumes a model and finds the best behaviour for a cost.
- Robust control assumes an uncertainty set and guarantees performance for every plant in it.
- Reinforcement learning estimates values and policies from data, with weaker guarantees unless safety structure is added.
The notes start from the smallest example I know: a scalar plant with one unknown number. That example already contains the central difficulty of adaptive control and the central proof technique. Every later section generalizes it. The background assumed is classical and state-space control; see Control Theory Basics, Modern, Multivariable, and Networked Control, and Topics in Nonlinear Systems.
| Part | Sections | Topic |
|---|---|---|
| A | 1 | A first adaptive controller |
| B | 2 | Mathematical tools: existence, Lyapunov, LaSalle, Barbalat, UUB |
| C | 3-6 | Adaptive control: estimation, MRAC, backstepping, robustness |
| D | 7 | Observers and the Kalman filter |
| E | 8 | Optimal control: PMP, HJB, LQR, LQG, MPC |
| F | 9 | Robust control: small gain, $H_\infty$, $\mu$ |
| G | 10 | Reinforcement learning, ADP, and safety |
| H | 11 | Comparison, proof checklist, formula sheet |
1. A First Adaptive Controller
1.1 The Problem
Consider the scalar plant
\[\dot x=a\,x+u,\]where $a$ is a constant we do not know. It might be positive, so the open-loop plant may be unstable. We want $x(t)\to0$.
If $a$ were known, the answer is immediate: $u=-(a+k)x$ with $k>0$ gives $\dot x=-kx$, exponentially stable.
1.2 Certainty Equivalence
Not knowing $a$, a natural idea is to use an estimate $\hat a(t)$ as if it were the truth (certainty equivalence):
\[u=-(\hat a+k)\,x.\]Define the parameter error $\tilde a=\hat a-a$. The closed loop becomes
\[\dot x=a x-(\hat a+k)x=-kx-\tilde a\,x.\]The question is how to update $\hat a$. If we choose badly, the term $-\tilde ax$ can destabilize the loop.
1.3 Designing the Update Law with a Lyapunov Function
Here is the key idea of Lyapunov-based adaptive control. Choose a candidate “energy” that includes both the state and the parameter error:
\[V(x,\tilde a)=\frac12x^2+\frac{1}{2\gamma}\tilde a^2,\qquad\gamma>0.\]Since $a$ is constant, $\dot{\tilde a}=\dot{\hat a}$. Differentiate along solutions:
\[\dot V=x\dot x+\frac1\gamma\tilde a\dot{\hat a} =-kx^2-\tilde a\,x^2+\frac1\gamma\tilde a\,\dot{\hat a} =-kx^2+\tilde a\Big(\frac1\gamma\dot{\hat a}-x^2\Big).\]We cannot compute the term containing $\tilde a$ (we do not know $a$), but we can cancel it by choosing
\[\dot{\hat a}=\gamma\,x^2.\]Then $\dot V=-kx^2\le0$.
1.4 What We Can Conclude, and What We Cannot
- $V$ is non-increasing, so $V(t)\le V(0)$. Both $x$ and $\tilde a$ are bounded.
- Integrating $\dot V=-kx^2$: $k\int_0^\infty x^2dt\le V(0)$, so $x\in\mathcal L_2$ (finite energy).
- $\dot x=-kx-\tilde ax$ is bounded because $x$ and $\tilde a$ are.
- A square-integrable signal with bounded derivative must tend to zero (Barbalat’s lemma, section 2.7). Hence $x(t)\to0$.
What we cannot conclude is $\hat a\to a$. The derivative $\dot V$ involves only $x$, so the Lyapunov argument says nothing about $\tilde a$ converging. Indeed, simulating with $a=2$, $k=1$, $x(0)=1$, $\hat a(0)=0$:
| Adaptation gain $\gamma$ | Final estimate $\hat a(\infty)$ | True $a$ |
|---|---|---|
| 0.5 | 2.22 | 2 |
| 1 | 2.41 | 2 |
| 5 | 3.45 | 2 |
In every case $x\to0$, but the estimate settles wherever the transient leaves it. Once $x=0$ there is nothing more to learn: the data contain no information about $a$. This is the first lesson of adaptive control: regulation or tracking does not require identification, and identification requires the signals to be rich enough (persistent excitation, section 3.3).
1.5 The Pattern
Every Lyapunov-based adaptive design in these notes follows the same five steps:
- Write the error dynamics with the parameter error appearing linearly.
- Choose $V$ = (tracking error energy) + (weighted parameter error energy).
- Differentiate and collect the terms containing the unknown parameter error.
- Choose the update law to cancel them.
- Conclude boundedness from $\dot V\le0$, then convergence of the tracking error from Barbalat or LaSalle.
What to Remember
- Certainty equivalence: use the estimate as if it were the true parameter.
- The update law is designed to cancel the unknown cross term in $\dot V$.
- The result is bounded signals and convergence of the error, not of the parameter estimate.
2. Mathematical Tools
The argument above used several facts that need care: that solutions exist, what “stable” means, and why “integrable with bounded derivative” implies convergence. This section collects the tools.
2.1 Existence, Uniqueness, and Finite Escape
Consider $\dot x=f(t,x)$, $x(t_0)=x_0$.
Theorem (local existence and uniqueness). If $f$ is piecewise continuous in $t$ and locally Lipschitz in $x$, i.e. $\lVert f(t,x)-f(t,y)\rVert\le L\lVert x-y\rVert$ near $x_0$, then there is a unique solution on some interval $[t_0,t_0+\delta]$. If $f$ is globally Lipschitz, the solution exists for all time.
Two examples show why the hypotheses matter.
- Non-uniqueness. $\dot x=x^{1/3}$, $x(0)=0$ has solutions $x\equiv0$ and $x(t)=(2t/3)^{3/2}$. The function $x^{1/3}$ is not Lipschitz at 0.
- Finite escape time. $\dot x=x^2$, $x(0)=1$ has the solution $x(t)=1/(1-t)$, which blows up at $t=1$. The function $x^2$ is locally but not globally Lipschitz.
Finite escape is a real danger in nonlinear and adaptive loops, because the closed loop contains products of states and estimates. The standard way out is the continuation property: if a solution is known to remain in a compact set, it exists for all time. This is why adaptive proofs always establish boundedness first, from $\dot V\le0$, and only then discuss convergence.
2.2 Equilibria and Linearization
An equilibrium $x_e$ satisfies $f(x_e)=0$. Near it, $\dot{\delta x}\approx J\,\delta x$ with $J=\partial f/\partial x$ evaluated at $x_e$. Lyapunov’s indirect method: if all eigenvalues of $J$ have negative real parts, $x_e$ is locally exponentially stable; if any has a positive real part, it is unstable; if some are on the imaginary axis, linearization is inconclusive.
For the pendulum $\ddot\theta=-\sin\theta-b\dot\theta$, the downward equilibrium has \(J=\begin{bmatrix}0&1\\-1&-b\end{bmatrix}\) (stable for $b>0$) and the upright one has \(J=\begin{bmatrix}0&1\\1&-b\end{bmatrix}\) (unstable).
2.3 Stability Definitions
For an equilibrium at the origin of $\dot x=f(x)$:
- Stable (in the sense of Lyapunov): for every $\varepsilon>0$ there is $\delta>0$ such that $\lVert x(0)\rVert<\delta$ implies $\lVert x(t)\rVert<\varepsilon$ for all $t\ge0$. Start close, stay close.
- Asymptotically stable: stable, and $x(t)\to0$ for initial conditions near 0.
- Exponentially stable: $\lVert x(t)\rVert\le c\lVert x(0)\rVert e^{-\lambda t}$.
- Globally asymptotically stable: asymptotic stability from every initial condition.
For time-varying systems $\dot x=f(t,x)$, these properties may depend on the initial time; uniform stability requires the constants to be independent of $t_0$. Adaptive closed loops with time-varying references are time-varying systems, which is why uniformity and Barbalat appear.
2.4 Lyapunov’s Direct Method
A function $V$ is positive definite if $V(0)=0$ and $V(x)>0$ for $x\neq0$; radially unbounded if $V(x)\to\infty$ as $\lVert x\rVert\to\infty$.
Theorem (Lyapunov). Let $V$ be continuously differentiable and positive definite.
- If $\dot V(x)=\nabla V(x)^\top f(x)\le0$, the origin is stable.
- If $\dot V(x)<0$ for $x\neq0$, it is asymptotically stable.
- If additionally $V$ is radially unbounded, it is globally asymptotically stable.
The beauty of the theorem is that it requires no solution of the differential equation, only the sign of a derivative.
Linear systems. For $\dot x=Ax$, try $V=x^\top Px$. Then $\dot V=x^\top(A^\top P+PA)x$, so we want the Lyapunov equation
\[A^\top P+PA=-Q,\qquad Q\succ0.\]It has a unique solution $P\succ0$ if and only if $A$ is Hurwitz. Worked example. \(A=\begin{bmatrix}0&1\\-2&-3\end{bmatrix}\) (eigenvalues $-1,-2$), $Q=I$. Writing \(P=\begin{bmatrix}p_1&p_2\\p_2&p_3\end{bmatrix}\) and matching entries gives $-4p_2=-1$, $p_1-3p_2-2p_3=0$, $2p_2-6p_3=-1$, so $p_2=\frac14$, $p_3=\frac14$, $p_1=\frac54$. The matrix \(P=\begin{bmatrix}5/4&1/4\\1/4&1/4\end{bmatrix}\) has eigenvalues $1.31$ and $0.19$: positive definite, as predicted. MRAC uses exactly this $P$ for the reference model.
2.5 LaSalle’s Invariance Principle
Often we can only show $\dot V\le0$, not $\dot V<0$. For the damped pendulum with energy $V=\frac12\dot\theta^2+(1-\cos\theta)$, $\dot V=-b\dot\theta^2$, which vanishes whenever $\dot\theta=0$, regardless of $\theta$.
Theorem (LaSalle, autonomous systems). If solutions are bounded and $\dot V\le0$, every solution converges to the largest invariant set contained in $\lbrace x:\dot V(x)=0\rbrace$.
For the pendulum: on $\lbrace\dot\theta=0\rbrace$, staying there requires $\ddot\theta=0$, so $\sin\theta=0$. Near the downward equilibrium the largest invariant set is the equilibrium itself, so it is asymptotically stable even though $\dot V$ is only semidefinite.
2.6 Why LaSalle Is Not Enough: Time-Varying Loops
LaSalle needs an autonomous system. In tracking problems the closed loop depends on a reference $r(t)$, so it is time-varying, and the invariance argument does not apply. We need a tool that works directly on signals.
2.7 Signal Norms and Barbalat’s Lemma
For signals on $[0,\infty)$: $x\in\mathcal L_\infty$ if it is bounded; $x\in\mathcal L_2$ if $\int_0^\infty\lVert x\rVert^2dt<\infty$.
- $e^{-t}$ is in both. $\sin t$ is in $\mathcal L_\infty$ but not $\mathcal L_2$. $1/(1+t)$ is in both, since $\int_0^\infty(1+t)^{-2}dt=1$.
- Being in $\mathcal L_2$ does not imply convergence to zero: a train of ever-narrower spikes of height 1 can have finite energy and never settle.
The missing ingredient is regularity of the derivative.
Barbalat’s lemma. If $f(t)$ has a finite limit as $t\to\infty$ and $\dot f$ is uniformly continuous, then $\dot f(t)\to0$.
The uniform continuity condition cannot be dropped: $f(t)=\sin(t^2)/t$ tends to 0, but $\dot f(t)=2\cos(t^2)-\sin(t^2)/t^2$ oscillates forever, because $\dot f$ wiggles faster and faster.
The version used in practice. If $g\in\mathcal L_2\cap\mathcal L_\infty$ and $\dot g\in\mathcal L_\infty$, then $g(t)\to0$. (A bounded derivative makes $g$ uniformly continuous; apply Barbalat to $\int_0^tg^2$.) This is exactly step 4 of section 1.4.
Lyapunov-like lemma. If $V(t,x)$ is bounded below, $\dot V\le0$, and $\dot V$ is uniformly continuous in time, then $\dot V\to0$. In adaptive proofs, $\dot V=-e^\top Qe$, so this gives $e\to0$.
2.8 Uniform Ultimate Boundedness
With disturbances we usually cannot prove convergence to zero, only convergence to a neighbourhood. A solution is uniformly ultimately bounded (UUB) with ultimate bound $b$ if, for every initial condition, it enters the ball of radius $b$ after a finite time and stays there.
The standard Lyapunov route: show
\[\dot V\le-cV+D,\qquad c,D>0.\]By the comparison lemma, $V(t)\le V(0)e^{-ct}+\frac Dc(1-e^{-ct})$, so $V$ is eventually below roughly $D/c$, which bounds the states. Robust adaptive control (section 6) proves results of exactly this form.
What to Remember
- Prove boundedness first (it also rules out finite escape), then convergence.
- Lyapunov: $V\succ0$, $\dot V\le0$ gives stability; $A^\top P+PA=-Q$ for linear systems.
- LaSalle for autonomous systems; Barbalat for time-varying ones: $g\in\mathcal L_2\cap\mathcal L_\infty$, $\dot g\in\mathcal L_\infty$ implies $g\to0$.
- With disturbances: $\dot V\le-cV+D$ gives UUB.
3. Online Parameter Estimation
Before adaptive control, consider adaptive estimation: learning parameters from measured signals, with no feedback loop to destabilize.
3.1 The Linear Parametric Model
Many plants can be written as
\[z(t)=\theta^{\ast\top}\phi(t),\]where $z$ and the regressor $\phi$ are computable from measurements and $\theta^\ast$ is the unknown parameter vector.
Example. A mass-spring-damper $m\ddot x+c\dot x+kx=u$ has $\theta^\ast=(m,c,k)$, but writing $u=[\ddot x,\ \dot x,\ x]\,\theta^\ast$ would require differentiating a noisy measurement twice. Instead, filter both sides by a stable filter $1/\Lambda(s)$ with $\Lambda(s)=(s+\lambda)^2$:
\[\underbrace{\frac{1}{\Lambda(s)}u}_{z}=\theta^{\ast\top}\underbrace{\Big[\frac{s^2}{\Lambda(s)}x,\ \frac{s}{\Lambda(s)}x,\ \frac{1}{\Lambda(s)}x\Big]^\top}_{\phi}.\]All filters are proper, so $z$ and $\phi$ are computed without differentiation.
3.2 Gradient and Least-Squares Estimators
Let $\hat\theta$ be the estimate and $\tilde\theta=\hat\theta-\theta^\ast$. Define the normalized estimation error
\[\varepsilon=\frac{z-\hat\theta^\top\phi}{m^2}=-\frac{\tilde\theta^\top\phi}{m^2},\qquad m^2=1+\phi^\top\phi.\]Normalization by $m^2$ keeps the update bounded even if $\phi$ grows.
Gradient estimator. Descend on $\frac12\varepsilon^2m^2$:
\[\dot{\hat\theta}=\Gamma\,\varepsilon\,\phi,\qquad\Gamma\succ0.\]With $V=\frac12\tilde\theta^\top\Gamma^{-1}\tilde\theta$: $\dot V=\tilde\theta^\top\varepsilon\phi=-\varepsilon^2m^2\le0$. So $\tilde\theta$ is bounded and $\varepsilon m\in\mathcal L_2$; the estimation error goes to zero.
Least-squares estimator. Minimizing the integrated squared error gives
\[\dot{\hat\theta}=P\,\varepsilon\,\phi,\qquad\dot P=-P\frac{\phi\phi^\top}{m^2}P,\]with $P(0)\succ0$. $P$ plays the role of an adaptive, direction-dependent gain; it shrinks in directions that have been well excited. Without a forgetting factor or covariance resetting, $P$ shrinks forever and the estimator stops tracking parameter changes.
3.3 Persistent Excitation
Small estimation error $\varepsilon$ only says $\tilde\theta^\top\phi\approx0$: the parameter error is orthogonal to the regressor. For $\tilde\theta\to0$ we need $\phi$ to point in every direction over time.
Definition. $\phi$ is persistently exciting (PE) if there are $T,\alpha>0$ with
\[\int_t^{t+T}\phi(\tau)\phi(\tau)^\top d\tau\succeq\alpha I\qquad\text{for all }t.\]Examples.
- $\phi=(\sin t,\ \cos t)$: over one period, $\int\phi\phi^\top=\pi I$. PE.
- $\phi=(\sin t,\ 2\sin t)$: the integral has rank 1. Not PE; only the combination $\theta_1+2\theta_2$ is identifiable.
With PE, the gradient and least-squares estimators converge exponentially. A useful rule of thumb: a regressor generated by a stable linear system needs a reference input containing at least $n/2$ distinct frequencies to excite $n$ parameters (a “sufficiently rich” input).
What to Remember
- Write the plant as $z=\theta^{\ast\top}\phi$; use stable filters to avoid differentiation.
- Gradient and least-squares estimators make the prediction error small.
- Parameter convergence needs persistent excitation.
4. Model Reference Adaptive Control
4.1 The Idea
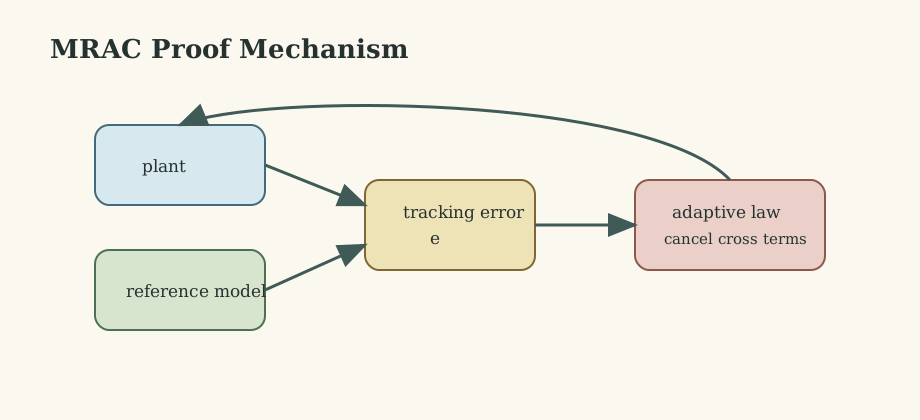
Specify the desired closed-loop behaviour as a reference model, a stable system driven by the command $r$, and adapt the controller so that the plant imitates the model.
4.2 Scalar MRAC, Fully Worked
Plant and reference model:
\[\dot x=ax+bu,\qquad\dot x_m=-a_mx_m+b_mr,\]with $a$, $b$ unknown, the sign of $b$ known, and $a_m>0$.
Matching. If we knew $a$ and $b$, the controller $u=k_x^\ast x+k_r^\ast r$ would make the plant identical to the model when $a+bk_x^\ast=-a_m$ and $bk_r^\ast=b_m$, i.e.
\[k_x^\ast=-\frac{a+a_m}{b},\qquad k_r^\ast=\frac{b_m}{b}.\]Adaptive controller. Use $u=\hat k_xx+\hat k_rr$, with errors $\Delta k_x=\hat k_x-k_x^\ast$, $\Delta k_r=\hat k_r-k_r^\ast$. Adding and subtracting the ideal gains, the tracking error $e=x-x_m$ obeys
\[\dot e=-a_me+b\,(\Delta k_x\,x+\Delta k_r\,r).\]Lyapunov function.
\[V=\frac12e^2+\frac{\lvert b\rvert}{2\gamma_x}\Delta k_x^2+\frac{\lvert b\rvert}{2\gamma_r}\Delta k_r^2.\]Derivative.
\[\dot V=-a_me^2+b\,e\,\Delta k_x\,x+b\,e\,\Delta k_r\,r+\frac{\lvert b\rvert}{\gamma_x}\Delta k_x\dot{\hat k}_x+\frac{\lvert b\rvert}{\gamma_r}\Delta k_r\dot{\hat k}_r.\]Cancel the unknown cross terms with
\[\dot{\hat k}_x=-\gamma_x\,\mathrm{sgn}(b)\,e\,x,\qquad\dot{\hat k}_r=-\gamma_r\,\mathrm{sgn}(b)\,e\,r.\](Check: $\frac{\lvert b\rvert}{\gamma_x}\Delta k_x(-\gamma_x\mathrm{sgn}(b)ex)=-b\,e\,\Delta k_x\,x$.) Then $\dot V=-a_me^2\le0$.
Conclusions. $e$, $\Delta k_x$, $\Delta k_r$ are bounded. For bounded $r$, $x_m$ is bounded (stable model), so $x=e+x_m$ is bounded, so $\dot e$ is bounded. Also $e\in\mathcal L_2$. By Barbalat, $e(t)\to0$: the plant asymptotically follows the reference model. The only plant knowledge used was the sign of $b$, which fixes the direction of adaptation.
4.3 State-Feedback MRAC for Multivariable Plants
Plant and reference model:
\[\dot x=Ax+B\Lambda u,\qquad\dot x_m=A_mx_m+B_mr,\]with $A$ unknown, $\Lambda$ an unknown diagonal matrix with positive entries (control effectiveness), $B$ known, and $A_m$ Hurwitz. Assume matching conditions: there exist ideal gains with $A+B\Lambda K_x^{\ast\top}=A_m$ and $B\Lambda K_r^{\ast\top}=B_m$.
Controller $u=\hat K_x^\top x+\hat K_r^\top r$; with $\Delta K=\hat K-K^\ast$, the error $e=x-x_m$ satisfies
\[\dot e=A_me+B\Lambda\big(\Delta K_x^\top x+\Delta K_r^\top r\big).\]Take $P\succ0$ solving $A_m^\top P+PA_m=-Q$ and
\[V=e^\top Pe+\mathrm{tr}\big(\Delta K_x^\top\Gamma_x^{-1}\Delta K_x\Lambda\big)+\mathrm{tr}\big(\Delta K_r^\top\Gamma_r^{-1}\Delta K_r\Lambda\big).\]Using the identity $e^\top PB\Lambda\Delta K_x^\top x=\mathrm{tr}(\Delta K_x^\top x\,e^\top PB\Lambda)$, the cross terms cancel with
\[\dot{\hat K}_x=-\Gamma_x\,x\,e^\top PB,\qquad\dot{\hat K}_r=-\Gamma_r\,r\,e^\top PB,\]leaving $\dot V=-e^\top Qe\le0$. The conclusions are the same as in the scalar case.
4.4 What MRAC Does and Does Not Guarantee
| MRAC gives | MRAC does not give |
|---|---|
| bounded closed-loop signals | parameter convergence (needs PE) |
| asymptotic tracking $e\to0$ | a bound on the transient (it can be large) |
| using only the sign of $b$ and matching | robustness to disturbances or unmodelled dynamics (section 6) |
Direct versus indirect. The design above is direct: it adapts controller gains. Indirect adaptive control estimates plant parameters (section 3) and computes the controller from them by certainty equivalence. Indirect designs separate estimation from control, but must avoid estimates that make the computed controller singular (e.g. $\hat b\approx0$).
Historical note. Early MRAC used the “MIT rule”, a gradient update $\dot\theta=-\gamma\,e\,\partial e/\partial\theta$ derived from a sensitivity argument. It works for small gains but can become unstable for large adaptation gains. Parks’ Lyapunov redesign (1966) replaced it with update laws like the ones above, for which stability is proved rather than hoped for.
Application. In a motion-control loop with an uncertain payload, the effective inertia (and hence $b$) changes. A fixed controller tuned for one payload becomes sluggish or oscillatory for another. MRAC adapts so the loop keeps behaving like the chosen reference model.
What to Remember
- MRAC: make the plant imitate a stable reference model; needs matching conditions and the sign of the input gain.
- Update law: $\dot{\hat K}=-\Gamma\,(\text{regressor})\,e^\top PB$, designed to cancel cross terms.
- Guarantees: boundedness and $e\to0$. Not parameter convergence, not transient bounds, not robustness.
5. Nonlinear Adaptive Control
5.1 Dynamic Inversion (Feedback Linearization)
For $\dot x=f(x)+g(x)u$ with output $y=h(x)$, differentiate $y$ until $u$ appears. If this happens after $r$ derivatives (the relative degree), we have $y^{(r)}=L_f^rh(x)+L_gL_f^{r-1}h(x)\,u$, and when $L_gL_f^{r-1}h\neq0$ the control
\[u=\frac{1}{L_gL_f^{r-1}h(x)}\big(-L_f^rh(x)+v\big)\]turns the input-output map into a chain of integrators, $y^{(r)}=v$. A linear controller for $v$ then places the poles. Two cautions: the remaining internal (zero) dynamics must be stable, and exact cancellation needs an exact model.
With unknown parameters. If the uncertainty enters as $f(x)=\theta^{\ast\top}\varphi(x)$ in the same equation as $u$ (a matched uncertainty), replace $\theta^\ast$ by $\hat\theta$ in the inversion and adapt $\hat\theta$ with a Lyapunov update, exactly as in section 1.
5.2 Backstepping Without Adaptation
When the uncertainty is not in the same equation as the input, inversion does not directly apply. Backstepping handles systems in strict-feedback form by designing a controller for one equation at a time, treating the next state as a “virtual control”.
Worked example. Stabilize
\[\dot x_1=x_1^2+x_2,\qquad\dot x_2=u.\]Step 1. Pretend $x_2$ is the input of the first equation. The virtual control $\alpha_1=-x_1^2-k_1x_1$ would give $\dot x_1=-k_1x_1$. Define $z_1=x_1$ and the error $z_2=x_2-\alpha_1$. Then $\dot z_1=-k_1z_1+z_2$, and with $V_1=\frac12z_1^2$,
\[\dot V_1=-k_1z_1^2+z_1z_2.\]Step 2. Now $\dot z_2=u-\dot\alpha_1=u+(2x_1+k_1)(x_1^2+x_2)$. With $V_2=V_1+\frac12z_2^2$,
\[\dot V_2=-k_1z_1^2+z_2\big[z_1+u+(2x_1+k_1)(x_1^2+x_2)\big].\]Choose $u=-z_1-k_2z_2-(2x_1+k_1)(x_1^2+x_2)$ to obtain $\dot V_2=-k_1z_1^2-k_2z_2^2$. The origin is globally asymptotically stable. Note the term $-z_1$ in $u$: it cancels the cross term $z_1z_2$ left over from step 1.
5.3 Adaptive Backstepping
Now let the first equation contain an unknown constant $\theta$:
\[\dot x_1=x_2+\theta\,\varphi_1(x_1),\qquad\dot x_2=u.\]Step 1. Virtual control $\alpha_1=-k_1x_1-\hat\theta\varphi_1(x_1)$, errors $z_1=x_1$, $z_2=x_2-\alpha_1$, $\tilde\theta=\hat\theta-\theta$. Then $\dot z_1=-k_1z_1+z_2-\tilde\theta\varphi_1$. With $V_1=\frac12z_1^2+\frac{1}{2\gamma}\tilde\theta^2$:
\[\dot V_1=-k_1z_1^2+z_1z_2+\tilde\theta\Big(\frac1\gamma\dot{\hat\theta}-z_1\varphi_1\Big).\]We could cancel the bracket now with $\dot{\hat\theta}=\gamma z_1\varphi_1$, but step 2 will produce more $\tilde\theta$ terms, so we postpone the choice.
Step 2. Since $\alpha_1$ depends on $x_1$ and $\hat\theta$,
\[\dot z_2=u-\frac{\partial\alpha_1}{\partial x_1}(x_2+\hat\theta\varphi_1)+\frac{\partial\alpha_1}{\partial x_1}\tilde\theta\varphi_1+\varphi_1\dot{\hat\theta}.\]With $V_2=V_1+\frac12z_2^2$, the $\tilde\theta$ terms in $\dot V_2$ are
\[\tilde\theta\Big(\frac1\gamma\dot{\hat\theta}-z_1\varphi_1+z_2\frac{\partial\alpha_1}{\partial x_1}\varphi_1\Big),\]which vanish with the update law (the “tuning function”)
\[\dot{\hat\theta}=\gamma\,\varphi_1\Big(z_1-z_2\frac{\partial\alpha_1}{\partial x_1}\Big).\]Then choose
\[u=-z_1-k_2z_2+\frac{\partial\alpha_1}{\partial x_1}(x_2+\hat\theta\varphi_1)-\varphi_1\dot{\hat\theta},\]where $\dot{\hat\theta}$ is the known expression above. The result is $\dot V_2=-k_1z_1^2-k_2z_2^2\le0$: bounded signals and $z\to0$ (by LaSalle-Yoshizawa). The same recursion extends to $n$ states, with one tuning function per step and a single parameter estimate, avoiding overparametrization.
Application. In a robotic joint with uncertain friction or payload, adaptive backstepping stabilizes the cascaded dynamics while estimating the uncertain coefficients, which is far more structured than “raise the gains and hope”.
What to Remember
- Dynamic inversion cancels known nonlinearities; adaptive inversion handles matched parametric uncertainty.
- Backstepping designs virtual controls step by step; each step adds a quadratic term to $V$.
- Adaptive backstepping postpones the update law until the last step (tuning functions).
6. Robustness of Adaptive Control
6.1 Parameter Drift: A Worked Failure
Return to the scalar controller of section 1, but add a small bounded disturbance $d$:
\[\dot x=ax+u+d,\qquad u=-(\hat a+k)x,\qquad\dot{\hat a}=\gamma x^2.\]The update law $\dot{\hat a}=\gamma x^2$ is never negative. With a persistent disturbance, $x$ never settles exactly at zero; it hovers near $d/(k+\tilde a)$. So $\hat a$ keeps increasing. Approximating $x\approx d/\hat a$ for large $\hat a$ gives $\dot{\hat a}\approx\gamma d^2/\hat a^2$, so
\[\hat a(t)\approx(3\gamma d^2t)^{1/3}\to\infty.\]A simulation with $a=k=\gamma=1$, $d=0.5$ confirms this: $\hat a\approx4.2$ at $t=100$, $9.1$ at $t=1000$, $15.5$ at $t=5000$, matching the formula. The state stays small, so the loop looks fine, but the feedback gain grows without bound. A high-gain loop is fragile: it amplifies measurement noise, excites unmodelled high-frequency dynamics, and can suddenly burst into oscillation. Rohrs and colleagues (1985) showed such instabilities in examples with small unmodelled dynamics. Ideal adaptive laws are not robust.
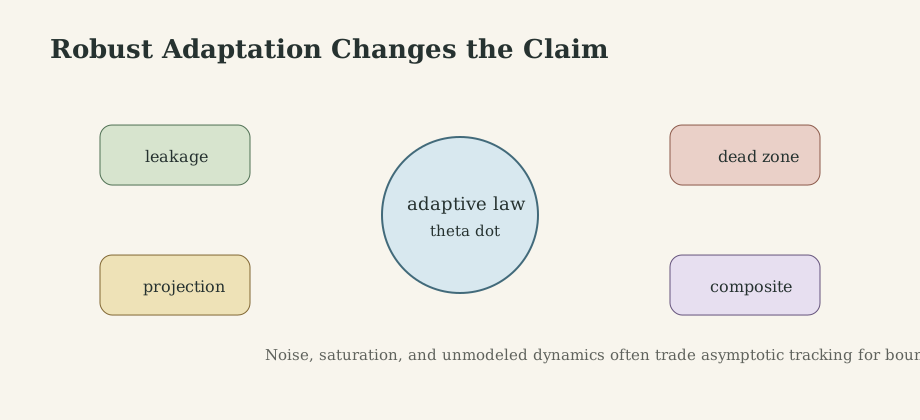
6.2 Sigma-Modification (Leakage)
The fix is to let the estimate “leak” back towards a nominal value (here zero):
\[\dot{\hat a}=\gamma\big(x^2-\sigma\hat a\big),\qquad\sigma>0.\]With the same $V=\frac12x^2+\frac{1}{2\gamma}\tilde a^2$ and $\lvert d\rvert\le d_0$:
\[\dot V=-kx^2+xd-\sigma\tilde a\hat a.\]Bound the two indefinite terms. Young’s inequality gives $xd\le\frac k2x^2+\frac{d_0^2}{2k}$. Writing $\hat a=\tilde a+a$,
\[-\sigma\tilde a\hat a=-\sigma\tilde a^2-\sigma\tilde aa\le-\frac\sigma2\tilde a^2+\frac\sigma2a^2.\]Therefore
\[\dot V\le-\frac k2x^2-\frac\sigma2\tilde a^2+\frac{d_0^2}{2k}+\frac{\sigma a^2}{2}\le-cV+D,\]with $c=\min(k,\sigma\gamma)$ and $D=\frac{d_0^2}{2k}+\frac{\sigma a^2}{2}$. By section 2.8, all signals are uniformly ultimately bounded. The price: even with $d=0$ we no longer get $x\to0$ exactly, because leakage biases the estimate. Robustness is bought with weaker asymptotic claims.
6.3 The Family of Robust Modifications
| Modification | Update law idea | What it buys | What it costs |
|---|---|---|---|
| $\sigma$-modification | add $-\sigma\Gamma\hat\theta$ | bounded estimates under disturbances | bias; no exact convergence |
| $e$-modification | leakage scaled by $\lvert e\rvert$ | leakage vanishes as error vanishes | more complex analysis |
| Projection | keep $\hat\theta$ in a known convex set | hard bounds on estimates; keeps $\hat b$ away from 0 | needs prior parameter bounds |
| Dead zone | stop adapting when $\lvert e\rvert$ is below a noise level | no drift from noise | residual error up to the dead zone |
| Normalization | divide updates by $1+\phi^\top\phi$ | bounded update speed for large signals | slower adaptation |
| Composite adaptation | add a prediction-error term $\dot{\hat\theta}=-\Gamma(Y^\top e+W^\top\varepsilon)$ | better parameter convergence, smoother transients | needs filtered regressors |
Projection deserves a remark: it modifies the update only when the estimate is on the boundary and pointing outward, and it satisfies $\tilde\theta^\top\mathrm{Proj}(\hat\theta,y)\le\tilde\theta^\top y$, so the Lyapunov argument goes through unchanged while the estimates stay bounded by construction.
Unknown control direction. If even the sign of $b$ is unknown, Nussbaum-type gains can still achieve regulation, but transients can be large and the designs are delicate.
6.4 Output Feedback
When only $y=Cx$ is measured, adaptation must be combined with state estimation. For known linear dynamics the observer of section 7 suffices, but in adaptive and nonlinear settings the estimation and parameter errors couple, and the clean separation of LQG does not hold. The Lyapunov function must include the observer error, and the proof handles all three errors together.
6.5 Practitioner Cautions: What Adaptive Control Is and Is Not
Four clarifications keep the theory honest. First, a general warning: adaptation does not by itself guarantee closed-loop stability. Every stability statement in this chapter is conditional on assumptions (a known plant structure with linear-in-parameters uncertainty, matching conditions, a known sign of the input gain, bounded references, and a Lyapunov-based adaptive law), and the conclusion is usually boundedness and asymptotic error convergence, not parameter convergence, robustness, or good transients. Break an assumption (unmodelled dynamics, disturbances, saturation, noise, delay, sampling) and the guarantee can vanish, as section 6.1 shows. They echo the practitioner’s view in Control Theory Basics.
(a) Adaptive is not the same as scheduled. If a parameter changes with an independently measured variable (EPS assist versus vehicle speed, for example), that is gain scheduling. Adaptive control adjusts parameters from the plant’s own input-output signals. The distinction matters because scheduling has a measured schedule and no estimator to destabilize.
(b) An adaptive controller is a fixed nonlinear controller of higher order. The adaptation law has fixed gains $\Gamma$; the parameter estimates are extra states. Nothing “learns” beyond what these dynamics encode. Seen this way, a large adaptation gain behaves like high-gain feedback that covers a wide parameter range, with the usual price: noise amplification, saturation, and sensitivity to unmodelled fast dynamics.
(c) Certainty equivalence can fail, with an explicit counterexample. Consider
\[\dot x=\theta x^2+u,\qquad u=-x-\hat\theta x^2,\qquad\tilde\theta=\theta-\hat\theta .\]Substituting gives $\dot x=-x+\tilde\theta x^2$. Assumption (stated explicitly): to isolate the effect, impose a “textbook-good” estimator error $\tilde\theta(t)=\tilde\theta_0e^{-t}$ from outside. This is a prescribed signal, not the output of a real update law driven by $x$; a real estimator would have its own dynamics, and the point is that exponential convergence of the estimate alone is not enough. With $\tilde\theta=0$ the loop $\dot x=-x$ is exponentially stable, yet
\[\dot x=-x+\tilde\theta_0e^{-t}x^2 .\]Substituting $z=1/x$ gives $\dot z=z-\tilde\theta_0e^{-t}$, so
\[z(t)=e^{t}\Big(\tfrac{1}{x_0}-\tfrac{\tilde\theta_0}{2}\big(1-e^{-2t}\big)\Big).\]Equivalently, $w=e^{t}x$ obeys $\dot w=\tilde\theta_0e^{-2t}w^2$, which has the same blow-up time because $e^{t}$ is finite. (This is the form with an $e^{-2t}$ factor; it describes $w=e^{t}x$, not $x$ itself.) The three cases are:
- $x_0\tilde\theta_0>2$: $z$ reaches zero at the finite time $t^\ast=-\tfrac12\ln\big(1-\tfrac{2}{x_0\tilde\theta_0}\big)$ and $x$ escapes in finite time. The estimate converges, but the state escapes first.
- $x_0\tilde\theta_0=2$ (boundary): no finite escape, but $x(t)=(2/\tilde\theta_0)e^{t}$ grows without bound.
- $x_0\tilde\theta_0<2$: $z>0$ for all time and $x\to0$.
General estimator rate. If the prescribed parameter error decays as $\tilde\theta(t)=\tilde\theta_0e^{-\lambda t}$, the same substitution gives $\dot z=z-\tilde\theta_0e^{-\lambda t}$ and
\[z(t)=e^{t}\Big(\tfrac{1}{x_0}-\tfrac{\tilde\theta_0}{1+\lambda}\big(1-e^{-(1+\lambda)t}\big)\Big),\]so finite escape occurs exactly when $x_0\tilde\theta_0>1+\lambda$, at $t^\ast=-\tfrac{1}{1+\lambda}\ln\big(1-\tfrac{1+\lambda}{x_0\tilde\theta_0}\big)$. For $\lambda=1$ the threshold is 2 (above); for a faster estimator with $\tilde\theta(t)=\tilde\theta_0e^{-2t}$ it is 3, so a faster estimator enlarges the safe set of initial conditions but never removes the escape. Under the earlier assumption $\tilde\theta_0e^{-2t}$ applied to the plant $\dot x=-x+\tilde\theta x^2$, the threshold is therefore $x_0\tilde\theta_0>3$, not 2.
| Numerical check (adaptive-step integration, relative tolerance $10^{-12}$, event at $ | x | =10^{8}$): with $\lambda=1$, $x_0=1$, $\tilde\theta_0=3$ the state passes $10^{8}$ at $t=0.549306$, matching $t^\ast$; $\tilde\theta_0=2.5$ and $2.1$ give $t=0.80472$ and $1.52226$, also matching, while $\tilde\theta_0=1.9$ and $1.5$ decay. With $\lambda=2$, $x_0=1$: $\tilde\theta_0=3.5$ and $3.1$ escape at $0.64864$ and $1.14466$ (predicted $0.648637$, $1.144662$), while $2.9$ and $2.5$ decay. The closed form $x=1/z$ agrees with the integrated trajectory to a relative error below $10^{-11}$ in both cases. Caveat: this checks the algebra of the example, with the estimator error prescribed. It does not show what a real update law does, which depends on $x$ itself. |
The lesson: convergence of the estimator plus stability of the nominal loop do not imply stability of the combination. Lyapunov-based adaptive designs (sections 4 and 5) avoid this by analyzing the joint $(x,\tilde\theta)$ system, and adaptive backstepping uses nonlinear-damping-type terms to dominate the cross term $\tilde\theta x^2$.
Three architectures, side by side. Gain scheduling, self-tuning (indirect), and model-reference (direct) adaptive control differ in where the information for the parameter change comes from:
 Gain scheduling              Self-tuning regulator (STR)             MRAC (direct)
 --------------               ---------------------------             -------------
 scheduling variable v        r -> [controller(theta^)] -> [plant] -> y       r -> [controller(theta)] -> [plant] -> y
        |                               ^                        |                    ^   (theta adapted)      |
        v                               |                        |                    |                        |
 r -> [C(v)] -> [plant] -> y     [design: theta^ -> gains]       |             [adaptation law] <---- e = y - y_m
                                         ^                       |                    ^
                                         |                       v              [reference model] <- r -> y_m
                                  [estimator: theta^ from u, y] <+
In scheduling the parameter change is a known function of a measured variable; there is no estimator, so no estimator-controller coupling, but the design is only as good as the scheduling variable. In the self-tuning regulator the plant parameters are estimated and the controller is recomputed from them (certainty equivalence), so the quality of the closed loop depends on the estimate and its excitation. In MRAC the controller parameters are adjusted directly to drive the model error $e=y-y_m$ to zero, and the adaptation law is chosen from a Lyapunov function so the cross terms cancel (section 4.2); this removes the design step but needs structure assumptions (relative degree, minimum phase, sign of the high-frequency gain).
(d) Persistent excitation conflicts with regulation. A closed loop that regulates well drives $x\to0$, so the regressor $\phi$ shrinks and parameters stop being excited. How much excitation is needed depends on the regressor structure: for a linear-in-parameters model $z=\theta^\top\phi$, the requirement is that $\int_t^{t+T}\phi\phi^\top d\tau\succeq\alpha I$ for some $\alpha,T>0$. When $\phi$ is built by passing a reference through LTI filters, one sinusoid contributes at most two independent directions, so for $n$ parameters a rule of thumb is on the order of $n/2$ distinct frequencies; this is not universal. Nonlinear regressors, repeated structure, or extra measured signals change the count, and some parameters can be identified from a single rich signal while others need more. This is why recursive least squares in closed loop can show parameter drift or a line of equivalent estimates (several $(\hat a,\hat b)$ pairs giving the same closed loop), and why “the controller adapted” does not imply “the model was identified”. For classical STR the other failure modes are: pole placement based on an inaccurate estimate, near pole-zero cancellations that make the design fragile, and, for direct MRAS, the need for a minimum-phase plant so that the controller can be parameterized.
Finally, adaptation fixes stability under parametric uncertainty; it does not by itself guarantee good transients. Transient quality must be designed (reference model, adaptation gain, projection bounds), and when the plant structure is unknown, no adaptive law substitutes for structural knowledge. This is the control-theory form of the no-free-lunch principle.
What to Remember
- Ideal adaptive laws drift under disturbances; the gain grows and robustness is lost.
- $\sigma$-modification, projection, dead zones, and normalization restore boundedness (UUB).
- Each modification changes the theorem: robustness is traded for exact convergence.
7. Observers and the Kalman Filter
7.1 Luenberger Observer
For $\dot x=Ax+Bu$, $y=Cx$, run a copy of the model corrected by the output error:
\[\dot{\hat x}=A\hat x+Bu+L(y-C\hat x).\]The estimation error $\tilde x=x-\hat x$ obeys $\dot{\tilde x}=(A-LC)\tilde x$. If $(A,C)$ is observable (equivalently, the observability matrix $[C;CA;\ldots;CA^{n-1}]$ has full rank), the eigenvalues of $A-LC$ can be placed anywhere, so the error decays as fast as we like. In practice, fast observers amplify noise; there is a trade-off.
Separation principle (LTI). With state feedback $u=-K\hat x$ using the estimate, the closed-loop eigenvalues are those of $A-BK$ together with those of $A-LC$. Controller and observer can be designed independently.
7.2 The Kalman Filter
If the plant has process noise and measurement noise,
\[\dot x=Ax+Bu+w,\qquad y=Cx+v,\]with white noises of covariances $W$ and $V$, the observer gain that minimizes the steady-state error covariance is the Kalman gain
\[L=PC^\top V^{-1},\qquad AP+PA^\top+W-PC^\top V^{-1}CP=0.\]The filter Riccati equation is the “dual” of the LQR Riccati equation in section 8.
In discrete time, the filter alternates two steps:
\[\text{predict:}\quad\hat x^-_k=A\hat x_{k-1}+Bu_{k-1},\qquad P^-_k=AP_{k-1}A^\top+W,\] \[\text{update:}\quad K_k=P^-_kC^\top(CP^-_kC^\top+V)^{-1},\quad\hat x_k=\hat x^-_k+K_k(y_k-C\hat x^-_k),\quad P_k=(I-K_kC)P^-_k.\]The gain $K_k$ balances trust in the model ($P^-$) against trust in the measurement ($V$). For nonlinear systems, the extended Kalman filter linearizes around the current estimate (see the Lie group note for the version used in robot state estimation).
 Figure 1. The Kalman filter as a loop of two steps, prediction and innovation (update), starting from an initial state $x_0$ and covariance $P_0$; inputs are orange, outputs blue. Source: File:Kalman-filter en.svg. License: CC BY-SA 4.0.

The figure contains the same recursion as above: the prediction step propagates the state and covariance through the model, and the innovation step corrects them with the gain $K_k$ in proportion to the measurement residual $z_k-Hx_k^-$. The covariances $W$ and $V$ are the only tuning knobs, and the gain they produce settles to a constant in steady state, so for a fixed linear model the filter is an ordinary fixed linear system whose frequency response should be checked.
7.3 Practical Cautions: Estimator and Controller Are One Loop
- An observer is a feedback design. With $u=-K\hat x$, the controller seen from the plant is the dynamic compensator $D(s)=K(sI-A+BK+LC)^{-1}L$ (for $D=0$ feedthrough), the loop gain is $D(s)G(s)$, and its margins are what matter. Fast $L$ shortens estimation transients but amplifies sensor noise and can erode phase margin near crossover.
- Separation holds for eigenvalues, not for margins. The classical LQR margins (gain margin $[1/2,\infty)$, phase margin $\ge60^\circ$) hold only under these assumptions: continuous time; an LTI plant with $(A,B)$ stabilizable and $(A,Q^{1/2})$ detectable; $Q\succeq0$, $R\succ0$; the infinite-horizon optimal gain $K=R^{-1}B^\top P$; exact full-state feedback (no observer); and the loop broken at the plant input. They follow from Kalman’s return-difference inequality $\big(I+K(j\omega I-A)^{-1}B\big)^{\mathsf H}R\big(I+K(j\omega I-A)^{-1}B\big)\succeq R$. The margins are stated for a single input, or per channel for a multi-input plant with diagonal $R$. They do not carry over to discrete time, finite-horizon LQR, MPC with constraints, delays, saturation, or unmodelled dynamics. The Kalman filter has the dual guarantee at the plant output under dual assumptions. Once the estimate replaces the true state, the combined LQG loop has no general margin guarantee (Doyle 1978); see section 8.7. Loop transfer recovery (LTR) restores LQR margins asymptotically by making the observer fast, and it requires a minimum-phase plant.
- Check the combined loop. A correctly modelled closed-loop simulation can reveal a sensitivity peak, provided it includes the plant, estimator, and controller together at realistic frequency content. The real concern is model uncertainty and neglected dynamics: a nominal simulation can look fine while a perturbed model, a delay, or an unmodelled mode shows a large $\lVert S\rVert_\infty$. Complement time simulation with frequency-domain checks (Bode and Nyquist of the loop, $S$ and $T$ peaks, singular-value plots) on perturbed models.
- Separate tunings. When estimator and controller are tuned independently, closely spaced poles can combine into a sharp sensitivity peak; verify the combined loop rather than each half.
- Estimators in series add lag. Each additional filter adds phase lag in the loop; use one deliberately designed estimator where possible.
- Duality, not identity. The filter and regulator Riccati equations are mathematically dual: $(A,C,W,V)$ for estimation maps to $(A^\top,B,Q,R)$-type terms for control. This duality makes results transfer between the problems, but they are not literally the same optimization: one minimizes error covariance under stochastic assumptions, the other a cost functional over trajectories.
- $Q$, $R$, $W$, $V$ are often tuning weights rather than measured covariances; treat them as loop-shaping knobs and check frequency-domain behavior.
What to Remember
- Observer error dynamics $A-LC$; observability allows arbitrary placement.
- LTI separation: design $K$ and $L$ independently.
- The Kalman filter is the optimal observer under Gaussian noise; its Riccati equation is dual to LQR’s.
8. Optimal Control
8.1 The Problem
Find an input $u(\cdot)$ on $[t_0,t_f]$ minimizing
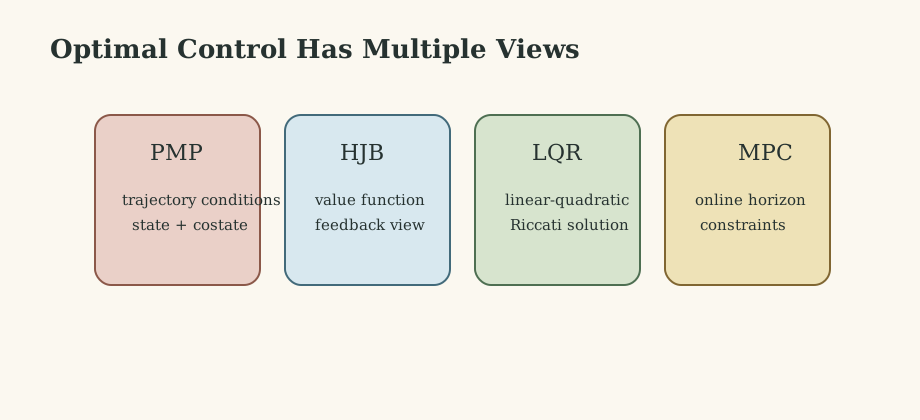
\[J=\phi\big(x(t_f)\big)+\int_{t_0}^{t_f}L(x,u,t)\,dt\qquad\text{subject to}\qquad\dot x=f(x,u,t),\ x(t_0)=x_0.\]There are two classical routes: Pontryagin’s principle, which gives conditions on an optimal trajectory, and dynamic programming, which gives an optimal feedback law. Both trace back to the calculus of variations.
8.2 From Calculus of Variations to Pontryagin
In the calculus of variations, a curve $x(t)$ minimizing $\int L(x,\dot x,t)dt$ must satisfy the Euler-Lagrange equation $\frac{d}{dt}\frac{\partial L}{\partial\dot x}=\frac{\partial L}{\partial x}$. For control problems, the dynamics are a constraint, so we adjoin them with a time-varying multiplier $\lambda(t)$, the costate. Define the Hamiltonian
\[H(x,u,\lambda,t)=L(x,u,t)+\lambda^\top f(x,u,t).\]Setting the first variation of the augmented cost to zero gives the necessary conditions of the Pontryagin minimum principle:
\[\dot x=\frac{\partial H}{\partial\lambda},\qquad \dot\lambda=-\frac{\partial H}{\partial x},\qquad u^\ast(t)=\arg\min_{u\in U}H(x^\ast,u,\lambda,t),\]with boundary conditions $x(t_0)=x_0$ and, if $x(t_f)$ is free, the transversality condition $\lambda(t_f)=\partial\phi/\partial x(t_f)$. The state runs forward from $x_0$, the costate backward from $t_f$: a two-point boundary value problem. The costate is the sensitivity of the optimal cost to the state.
8.3 Worked Example: Minimum-Energy Transfer
Move a double integrator $\dot x_1=x_2$, $\dot x_2=u$ from rest at $x_1=0$ to rest at $x_1=1$ in time $t_f=1$, minimizing $J=\frac12\int_0^1u^2dt$.
- Hamiltonian: $H=\frac12u^2+\lambda_1x_2+\lambda_2u$.
- Costate: $\dot\lambda_1=0$, $\dot\lambda_2=-\lambda_1$, so $\lambda_1=c_1$, $\lambda_2=-c_1t+c_2$.
- Minimize $H$ in $u$: $u=-\lambda_2=c_1t-c_2$.
- Integrate: $x_2=\frac{c_1}2t^2-c_2t$, $x_1=\frac{c_1}6t^3-\frac{c_2}2t^2$.
- Boundary conditions $x_2(1)=0$ and $x_1(1)=1$: $c_2=c_1/2$ and $c_1\big(\frac16-\frac14\big)=1$, so $c_1=-12$, $c_2=-6$.
The optimal control is $u^\ast(t)=6-12t$: accelerate, then brake, linearly. The position is $x_1(t)=3t^2-2t^3$, and the minimum cost is $J=\frac12\int_0^1(6-12t)^2dt=6$.
8.4 Worked Example: Minimum Time and Bang-Bang Control
Same plant, now with $\lvert u\rvert\le1$, minimizing the time to reach the origin: $J=\int_0^{t_f}1\,dt$. The Hamiltonian $H=1+\lambda_1x_2+\lambda_2u$ is linear in $u$, so it is minimized at the boundary:
\[u^\ast=-\mathrm{sgn}(\lambda_2).\]Since $\lambda_2$ is linear in $t$, it changes sign at most once: the optimal control is bang-bang with at most one switch. Tracing the trajectories that reach the origin with $u=\pm1$ gives the switching curve $x_1=-\frac12x_2\lvert x_2\rvert$: apply $u=-1$ above it, $u=+1$ below it, and switch on reaching it. This is a feedback law obtained from an open-loop principle, and an example of why optimal controls often saturate actuators.
8.5 Dynamic Programming and the HJB Equation
Bellman’s principle of optimality: the tail of an optimal trajectory is optimal for the tail problem. Let $V(x,t)$ be the optimal cost-to-go from state $x$ at time $t$. Over a short interval $dt$,
\[V(x,t)=\min_u\Big[L(x,u,t)\,dt+V\big(x+f(x,u,t)\,dt,\ t+dt\big)\Big].\]Expanding $V$ to first order and cancelling $V(x,t)$ gives the Hamilton-Jacobi-Bellman equation
\[-\frac{\partial V}{\partial t}=\min_u\Big[L(x,u,t)+\nabla_xV^\top f(x,u,t)\Big],\qquad V(x,t_f)=\phi(x).\]The minimizing $u$ is an optimal feedback law $u^\ast(x,t)$. The connection to Pontryagin: along an optimal trajectory, $\lambda(t)=\nabla_xV(x^\ast(t),t)$, and the bracket is the Hamiltonian. HJB is a PDE in $n$ dimensions, so solving it exactly is hopeless in general (the “curse of dimensionality”). It is solvable in closed form in one crucial case.
8.6 The Linear Quadratic Regulator
For $\dot x=Ax+Bu$ and $J=\int_0^\infty(x^\top Qx+u^\top Ru)\,dt$ with $Q\succeq0$, $R\succ0$, try $V(x)=x^\top Px$. The HJB equation (time-invariant, so $\partial V/\partial t=0$) becomes
\[0=\min_u\Big[x^\top Qx+u^\top Ru+2x^\top P(Ax+Bu)\Big].\]Setting the gradient in $u$ to zero: $u^\ast=-R^{-1}B^\top Px$. Substituting back, the equation must hold for all $x$, which gives the algebraic Riccati equation (ARE)
\[A^\top P+PA-PBR^{-1}B^\top P+Q=0.\]If $(A,B)$ is stabilizable and $(A,Q^{1/2})$ detectable, there is a unique stabilizing solution $P\succeq0$, and $u=-Kx$ with $K=R^{-1}B^\top P$ is optimal and stabilizing.
Worked scalar example. $\dot x=ax+bu$, $J=\int(qx^2+ru^2)dt$. The ARE is $2ap-\frac{b^2}{r}p^2+q=0$, with stabilizing root
\[p=\frac{r}{b^2}\Big(a+\sqrt{a^2+\frac{b^2q}{r}}\Big),\qquad a-\frac{b^2p}{r}=-\sqrt{a^2+\frac{b^2q}{r}}.\]For $a=b=q=r=1$ (an unstable plant), $p=1+\sqrt2\approx2.414$, $K=2.414$, and the closed-loop pole is at $-\sqrt2$. The limits are instructive:
- Cheap control ($r\to0$): the pole goes to $-\infty$; aggressive control.
- Expensive control ($r\to\infty$): the pole goes to $-\lvert a\rvert$. An unstable open-loop pole is mirrored into the left half-plane, the least control effort that still stabilizes.
Robustness for free. For SISO LQR (and MIMO with diagonal $R$), the loop has gain margin $[\frac12,\infty)$ and phase margin at least $60^\circ$. These margins come from the return-difference inequality $\lvert1+L(j\omega)\rvert\ge1$.
Finite horizon and discrete time. On $[0,t_f]$ with terminal weight $S$, $P(t)$ solves the Riccati differential equation $-\dot P=A^\top P+PA-PBR^{-1}B^\top P+Q$ backward from $P(t_f)=S$, and the gain is time-varying. In discrete time, $x_{k+1}=Ax_k+Bu_k$, the gain is $K=(R+B^\top PB)^{-1}B^\top PA$ with
\[P=Q+A^\top PA-A^\top PB(R+B^\top PB)^{-1}B^\top PA.\]8.7 LQG and Its Missing Margins
Combining LQR with a Kalman filter gives LQG (linear-quadratic-Gaussian) control, which is optimal for linear plants with Gaussian noise, by the separation principle. But the beautiful LQR margins do not survive. Doyle’s 1978 paper “Guaranteed Margins for LQG Regulators” has a famous one-word abstract: “There are none.” LQG designs can be arbitrarily fragile, which was a major motivation for robust control (section 9). Loop transfer recovery partially restores the margins.
8.8 Model Predictive Control
LQR cannot handle constraints such as actuator limits or safe state regions. Model predictive control solves, at each sampling instant, a finite-horizon constrained problem from the current measured state:
\[\min_{u_0,\ldots,u_{N-1}}\ \sum_{k=0}^{N-1}\big(x_k^\top Qx_k+u_k^\top Ru_k\big)+x_N^\top P_fx_N\]subject to $x_{k+1}=Ax_k+Bu_k$, $x_k\in\mathcal X$, $u_k\in\mathcal U$, $x_N\in\mathcal X_f$. It applies only the first input $u_0$, then repeats at the next sample (receding horizon). For linear dynamics and polyhedral constraints, each problem is a quadratic program.
Feedback enters through re-optimization from the measured state. Stability is not automatic for a finite horizon; the standard recipe chooses the terminal cost $P_f$ as the LQR Riccati solution and the terminal set $\mathcal X_f$ as an invariant set where the LQR law satisfies the constraints. This guarantees recursive feasibility and makes the optimal cost a Lyapunov function.
What to Remember
- PMP: Hamiltonian, costate running backward, $u^\ast$ minimizes $H$; gives trajectories (e.g. $u^\ast=6-12t$, bang-bang).
- HJB: PDE for the cost-to-go; gives feedback; $\lambda=\nabla V$.
- LQR: $V=x^\top Px$, ARE, $K=R^{-1}B^\top P$; $60^\circ$ phase margin. LQG: no guaranteed margins.
- MPC: repeated constrained optimization; terminal cost and set for stability.
9. Robust Control
9.1 Describing Uncertainty
Adaptive control assumes uncertainty is a few unknown constants. Robust control assumes the plant lies in a set, for example a nominal model with a bounded multiplicative uncertainty:
\[G_p(s)=G(s)\big(1+W(s)\Delta(s)\big),\qquad\lVert\Delta\rVert_\infty\le1,\]where $W(s)$ describes how large the relative model error can be at each frequency (typically small at low frequency, large at high frequency where models are poor).
9.2 The H-infinity Norm and the Small-Gain Theorem
For a stable transfer matrix, the $H_\infty$ norm is its peak gain over frequency,
\[\lVert G\rVert_\infty=\sup_\omega\sigma_{\max}\big(G(j\omega)\big),\]which equals the worst-case ratio of output energy to input energy. Examples: $\frac{1}{s+1}$ has $\lVert G\rVert_\infty=1$ (at $\omega=0$); the lightly damped $\frac{1}{s^2+0.2s+1}$ has a resonant peak of about $5.03$ near $\omega\approx0.99$.
Small-gain theorem. If $M$ and $\Delta$ are stable and $\lVert M\rVert_\infty\lVert\Delta\rVert_\infty<1$, their feedback interconnection is stable. Applied to multiplicative uncertainty, the closed loop is robustly stable for all admissible $\Delta$ if and only if
\[\lVert W\,T\rVert_\infty<1,\qquad T=\frac{GK}{1+GK}.\]9.3 Sensitivity Trade-offs and Mixed Sensitivity
The sensitivity $S=(1+GK)^{-1}$ maps disturbances to outputs (we want it small at low frequency, for tracking and disturbance rejection); the complementary sensitivity $T$ maps noise to outputs and determines robust stability (we want it small at high frequency). Since $S+T=1$, they cannot both be small at the same frequency. Mixed-sensitivity $H_\infty$ design finds a controller with
\[\left\lVert\begin{bmatrix}W_1S\\W_3T\end{bmatrix}\right\rVert_\infty<1,\]where the weights encode the performance and robustness requirements frequency by frequency. The resulting synthesis problem is solved by two Riccati equations (or LMIs), and the controller has the order of the plant plus weights.
9.4 Multivariable Systems and μ
For MIMO systems, gains depend on direction. The singular values of $G(j\omega)$ give the largest and smallest gains at each frequency, and a large ratio between them (an ill-conditioned plant) means some input directions barely affect the output. When the uncertainty has structure (several independent uncertain blocks, e.g. one per actuator), the small-gain test is conservative. The structured singular value $\mu$ measures the smallest structured perturbation that destabilizes the loop. $\mu$-synthesis by D-K iteration alternates between an $H_\infty$ controller design (K step) and fitting frequency-dependent scalings (D step); it is not guaranteed to find the global optimum but works well in practice.
9.5 Comparison with Adaptive Control and ADRC
Adaptive control says: learn the unknown parameters while staying stable. Robust control says: guarantee performance for every plant in the set, without learning. Robust designs give hard worst-case guarantees but can be conservative when the uncertainty set is large; adaptive designs can recover performance but need structural assumptions and robust modifications. Active disturbance rejection control (ADRC) takes a third route: lump all uncertainty into an extra state, estimate it with an extended state observer, and cancel it. It is practical and popular in industry, with a different style of guarantee (bounded estimation error under bounded disturbance derivatives).
What to Remember
- Uncertainty sets plus the small-gain theorem give robust stability: $\lVert WT\rVert_\infty<1$.
- $S+T=1$: performance at low frequency, robustness at high frequency; mixed-sensitivity weights encode both.
- $\mu$ handles structured uncertainty; D-K iteration designs for it.
10. Reinforcement Learning and Adaptive Dynamic Programming
10.1 From HJB to Bellman
In discrete time with discount factor $\gamma\in(0,1]$ and stage cost $c(x,u)$, dynamic programming gives the Bellman optimality equation
\[V^\ast(x)=\min_u\Big[c(x,u)+\gamma\,\mathbb E\,V^\ast(x')\Big],\]the discrete-time counterpart of HJB. (RL texts usually maximize reward instead of minimizing cost; the mathematics is the same.) Two classical algorithms solve it when the model is known:
- Value iteration: repeatedly apply the right-hand side to a guess of $V$.
- Policy iteration: alternate policy evaluation (compute the cost $V^\pi$ of the current policy, a linear equation) and policy improvement (choose the greedy policy with respect to $V^\pi$).
Reinforcement learning replaces the known model with samples of \((x,u,c,x')\) from interaction or simulation, and replaces exact tables with function approximation.
10.2 Policy Iteration for LQR: Kleinman’s Algorithm
For LQR, policy iteration has a beautiful closed form. Start with any stabilizing gain $K_0$. Repeat:
- Evaluate: solve the Lyapunov equation $(A-BK_i)^\top P_i+P_i(A-BK_i)+Q+K_i^\top RK_i=0$.
- Improve: $K_{i+1}=R^{-1}B^\top P_i$.
Each step solves a linear equation instead of the quadratic ARE, every $K_i$ remains stabilizing, and the iteration converges quadratically to the ARE solution.
Worked example. The scalar plant of section 8.6 ($a=b=q=r=1$). Policy evaluation gives $P_i=\frac{1+K_i^2}{2(K_i-1)}$ and improvement $K_{i+1}=P_i$. Starting from $K_0=2$:
| $i$ | $K_i$ | $P_i$ |
|---|---|---|
| 0 | 2 | 2.5 |
| 1 | 2.5 | 2.41667 |
| 2 | 2.41667 | 2.4142157 |
| 3 | 2.4142157 | 2.41421356237 |
The optimum is $1+\sqrt2=2.41421356237$; the number of correct digits roughly doubles each iteration, just as with Newton’s method (Kleinman’s algorithm is Newton’s method on the ARE).
10.3 Learning Without the Model: Integral Reinforcement Learning
Policy evaluation above needs $A$. Integral reinforcement learning (Vrabie and Lewis) avoids it by writing the Bellman equation over a time interval $T$ along measured trajectories under the current policy:
\[x(t)^\top P_ix(t)=\int_t^{t+T}\big(x^\top Qx+u^\top Ru\big)\,d\tau+x(t+T)^\top P_ix(t+T).\]This equation is linear in the entries of $P_i$, and every quantity in it is measured. Collecting enough intervals gives a least-squares problem for $P_i$ (it needs excitation, just like section 3.3). The improvement step $K_{i+1}=R^{-1}B^\top P_i$ still needs $B$, and off-policy variants (Jiang and Jiang) remove that requirement too. This line of work, adaptive dynamic programming, is where adaptive control and RL meet: it learns optimal controllers online, with convergence and stability guarantees inherited from Kleinman’s algorithm.
10.4 Model-Free RL Methods in Brief
- Q-learning learns the action-value function $Q(x,u)$, the cost of taking $u$ in $x$ and acting optimally afterwards, with the update \(Q\leftarrow Q+\alpha\big[c+\gamma\min_{u'}Q(x',u')-Q\big]\). Once $Q$ is known, $u^\ast(x)=\arg\min_uQ(x,u)$ needs no model.
- Policy gradient methods adjust a parameterized policy $\pi_\vartheta$ directly along an estimate of $\nabla_\vartheta J$.
- Actor-critic methods combine both: a critic estimates the value (an approximate HJB solution), and an actor improves the policy (the minimization in HJB).
10.5 Where Learning Belongs in a Feedback System
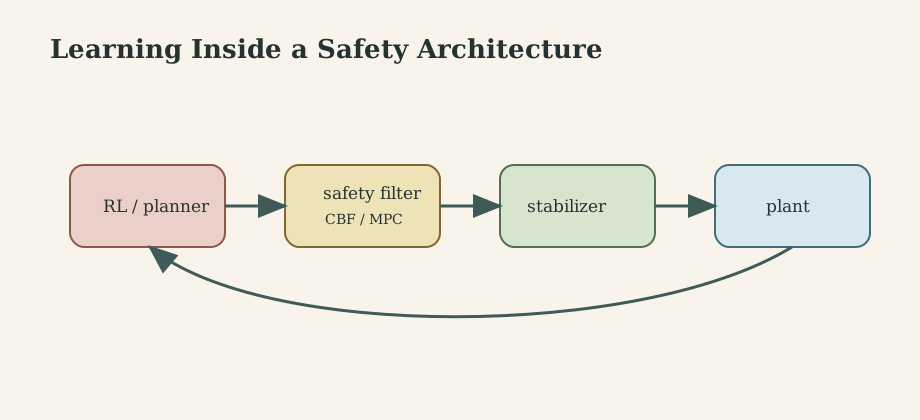
RL is strongest when simulation is cheap, models are incomplete, and objectives are long-horizon. It is risky when exploration is unsafe, data are scarce, or worst-case guarantees are required. In engineered systems, learning should sit inside a safety architecture: a robust or adaptive inner loop, a predictive or learned outer loop, and a safety filter between the learned policy and the plant.
Control barrier functions. Let the safe set be $\mathcal C=\lbrace x:h(x)\ge0\rbrace$. If the input keeps
\[\dot h(x,u)=\nabla h^\top\big(f(x)+g(x)u\big)\ge-\alpha\big(h(x)\big)\]for a class-$\mathcal K$ function $\alpha$, then $\mathcal C$ is forward invariant: the state never leaves. A CBF safety filter solves, at each instant, the small quadratic program
\[u=\arg\min_v\lVert v-u_{\text{RL}}\rVert^2\quad\text{s.t.}\quad\nabla h^\top(f+gv)\ge-\alpha(h),\]changing the learned input as little as possible to remain safe.
Worked example. A single integrator $\dot x=u$ must stay below $x=1$. With $h=1-x$, the condition is $-u\ge-\alpha(1-x)$, i.e. $u\le\alpha(1-x)$ for linear $\alpha$. The filter is simply $u=\min\big(u_{\text{RL}},\ \alpha(1-x)\big)$: far from the boundary the learned input passes through; near it, the allowed velocity shrinks to zero.
What to Remember
- Bellman = discrete HJB; value and policy iteration solve it with a model; RL uses samples.
- Kleinman’s algorithm is policy iteration (and Newton’s method) for LQR; integral RL performs it from data.
- Put learning inside a safety architecture; CBF filters minimally modify unsafe actions.
11. Comparison, Proof Checklist, and Formula Sheet
11.1 Comparing Guarantees
| Paradigm | Uncertainty model | Typical guarantee | Main weakness |
|---|---|---|---|
| Adaptive | unknown constant parameters, known structure | bounded signals, $e\to0$; UUB with robust modifications | wrong structure, poor transients, no parameter convergence without PE |
| Optimal (LQR/MPC) | known model | optimality for the cost; stability via Riccati or terminal ingredients | model sensitivity (LQG has no margins) |
| Robust ($H_\infty$, $\mu$) | uncertainty set | worst-case stability and performance | conservatism |
| RL / ADP | unknown model, data available | convergence of learning (ADP); average performance (deep RL) | safety, data, weak guarantees without structure |
The strongest real systems combine them: a robust or adaptive inner loop for stability, a predictive layer for constraints and performance, and learning on top, filtered for safety.
11.2 Proof Checklist
- State the uncertainty class (parameters, bounded disturbance, set, stochastic) precisely.
- State regularity assumptions (Lipschitz, matching, sign of input gain, boundedness of references).
- Write the error dynamics with the unknowns appearing linearly.
- Choose $V$ (or the value function) explicitly; differentiate carefully; isolate cross terms.
- Design the update or control law to cancel or bound those terms.
- Conclude boundedness first; then convergence via LaSalle (autonomous) or Barbalat (time-varying), or UUB via $\dot V\le-cV+D$.
- State exactly what was proved (boundedness, asymptotic tracking, UUB, optimality, worst-case attenuation) and what breaks under noise, saturation, sampling, or delays.
11.3 Formula Sheet
- Lyapunov equation: $A^\top P+PA=-Q$.
- Barbalat (practical form): $g\in\mathcal L_2\cap\mathcal L_\infty$, $\dot g\in\mathcal L_\infty\Rightarrow g\to0$.
- UUB: $\dot V\le-cV+D\Rightarrow\limsup V\le D/c$.
- Gradient estimator: $\dot{\hat\theta}=\Gamma\varepsilon\phi$, $\varepsilon=(z-\hat\theta^\top\phi)/m^2$.
- PE: $\int_t^{t+T}\phi\phi^\top d\tau\succeq\alpha I$.
- MRAC: \(\dot{\hat K}_x=-\Gamma_xxe^\top PB\), \(\dot{\hat K}_r=-\Gamma_rre^\top PB\).
- $\sigma$-modification: $\dot{\hat\theta}=\Gamma(\phi e-\sigma\hat\theta)$ (sign conventions as in the design).
- PMP: $H=L+\lambda^\top f$, $\dot\lambda=-\partial H/\partial x$, $u^\ast=\arg\min H$.
- HJB: $-V_t=\min_u\lbrace L+\nabla V^\top f\rbrace$.
- CT ARE: $A^\top P+PA-PBR^{-1}B^\top P+Q=0$, $K=R^{-1}B^\top P$.
- DT ARE: $P=Q+A^\top PA-A^\top PB(R+B^\top PB)^{-1}B^\top PA$.
- Kalman gain (DT): $K=P^-C^\top(CP^-C^\top+V)^{-1}$.
- Kleinman: $(A-BK_i)^\top P_i+P_i(A-BK_i)+Q+K_i^\top RK_i=0$, $K_{i+1}=R^{-1}B^\top P_i$.
- Small gain: $\lVert M\rVert_\infty\lVert\Delta\rVert_\infty<1$. Robust stability: $\lVert WT\rVert_\infty<1$.
- CBF condition: $\nabla h^\top(f+gu)\ge-\alpha(h)$.
References and Reading Guide
- P. A. Ioannou and J. Sun, Robust Adaptive Control (Prentice Hall, 1996; Dover reprint). Chapters 3 (stability tools, Barbalat), 4 (parameter identification, PE), 6 (MRAC), 8 (robust modifications).
- K. S. Narendra and A. M. Annaswamy, Stable Adaptive Systems (Prentice Hall, 1989).
- E. Lavretsky and K. A. Wise, Robust and Adaptive Control with Aerospace Applications (Springer, 2013). Clear MRAC derivations with $\Lambda$ uncertainty and projection.
- M. Krstić, I. Kanellakopoulos, and P. Kokotović, Nonlinear and Adaptive Control Design (Wiley, 1995). Backstepping and tuning functions.
- H. K. Khalil, Nonlinear Systems (3rd ed., Prentice Hall, 2002). Chapters 3 (existence and uniqueness), 4 (Lyapunov, LaSalle), 8 (Barbalat and boundedness), 13 (feedback linearization), 14 (backstepping).
- D. E. Kirk, Optimal Control Theory: An Introduction (Dover). Calculus of variations, PMP, dynamic programming.
- F. L. Lewis, D. Vrabie, and V. L. Syrmos, Optimal Control (3rd ed., Wiley, 2012). LQR, Riccati equations, and the chapter on reinforcement learning and adaptive dynamic programming.
- J. C. Doyle, “Guaranteed Margins for LQG Regulators,” IEEE TAC 23(4), 1978.
- S. Skogestad and I. Postlethwaite, Multivariable Feedback Control (2nd ed., Wiley, 2005). Sensitivity, $H_\infty$, $\mu$.
- J. B. Rawlings, D. Q. Mayne, and M. Diehl, Model Predictive Control: Theory, Computation, and Design (2nd ed., Nob Hill, 2017).
- D. L. Kleinman, “On an Iterative Technique for Riccati Equation Computations,” IEEE TAC 13(1), 1968.
- D. Vrabie and F. L. Lewis, “Neural Network Approach to Continuous-Time Direct Adaptive Optimal Control for Partially Unknown Nonlinear Systems,” Neural Networks 22(3), 2009.
- A. D. Ames et al., “Control Barrier Functions: Theory and Applications,” European Control Conference, 2019.
- D. P. Bertsekas, Dynamic Programming and Optimal Control (4th ed., Athena Scientific, 2017).